RefactorPlatform
An Open-Source Harness for Controlled Evaluation of Repository-Scale Refactoring Agents
*Equal contribution.
Abstract
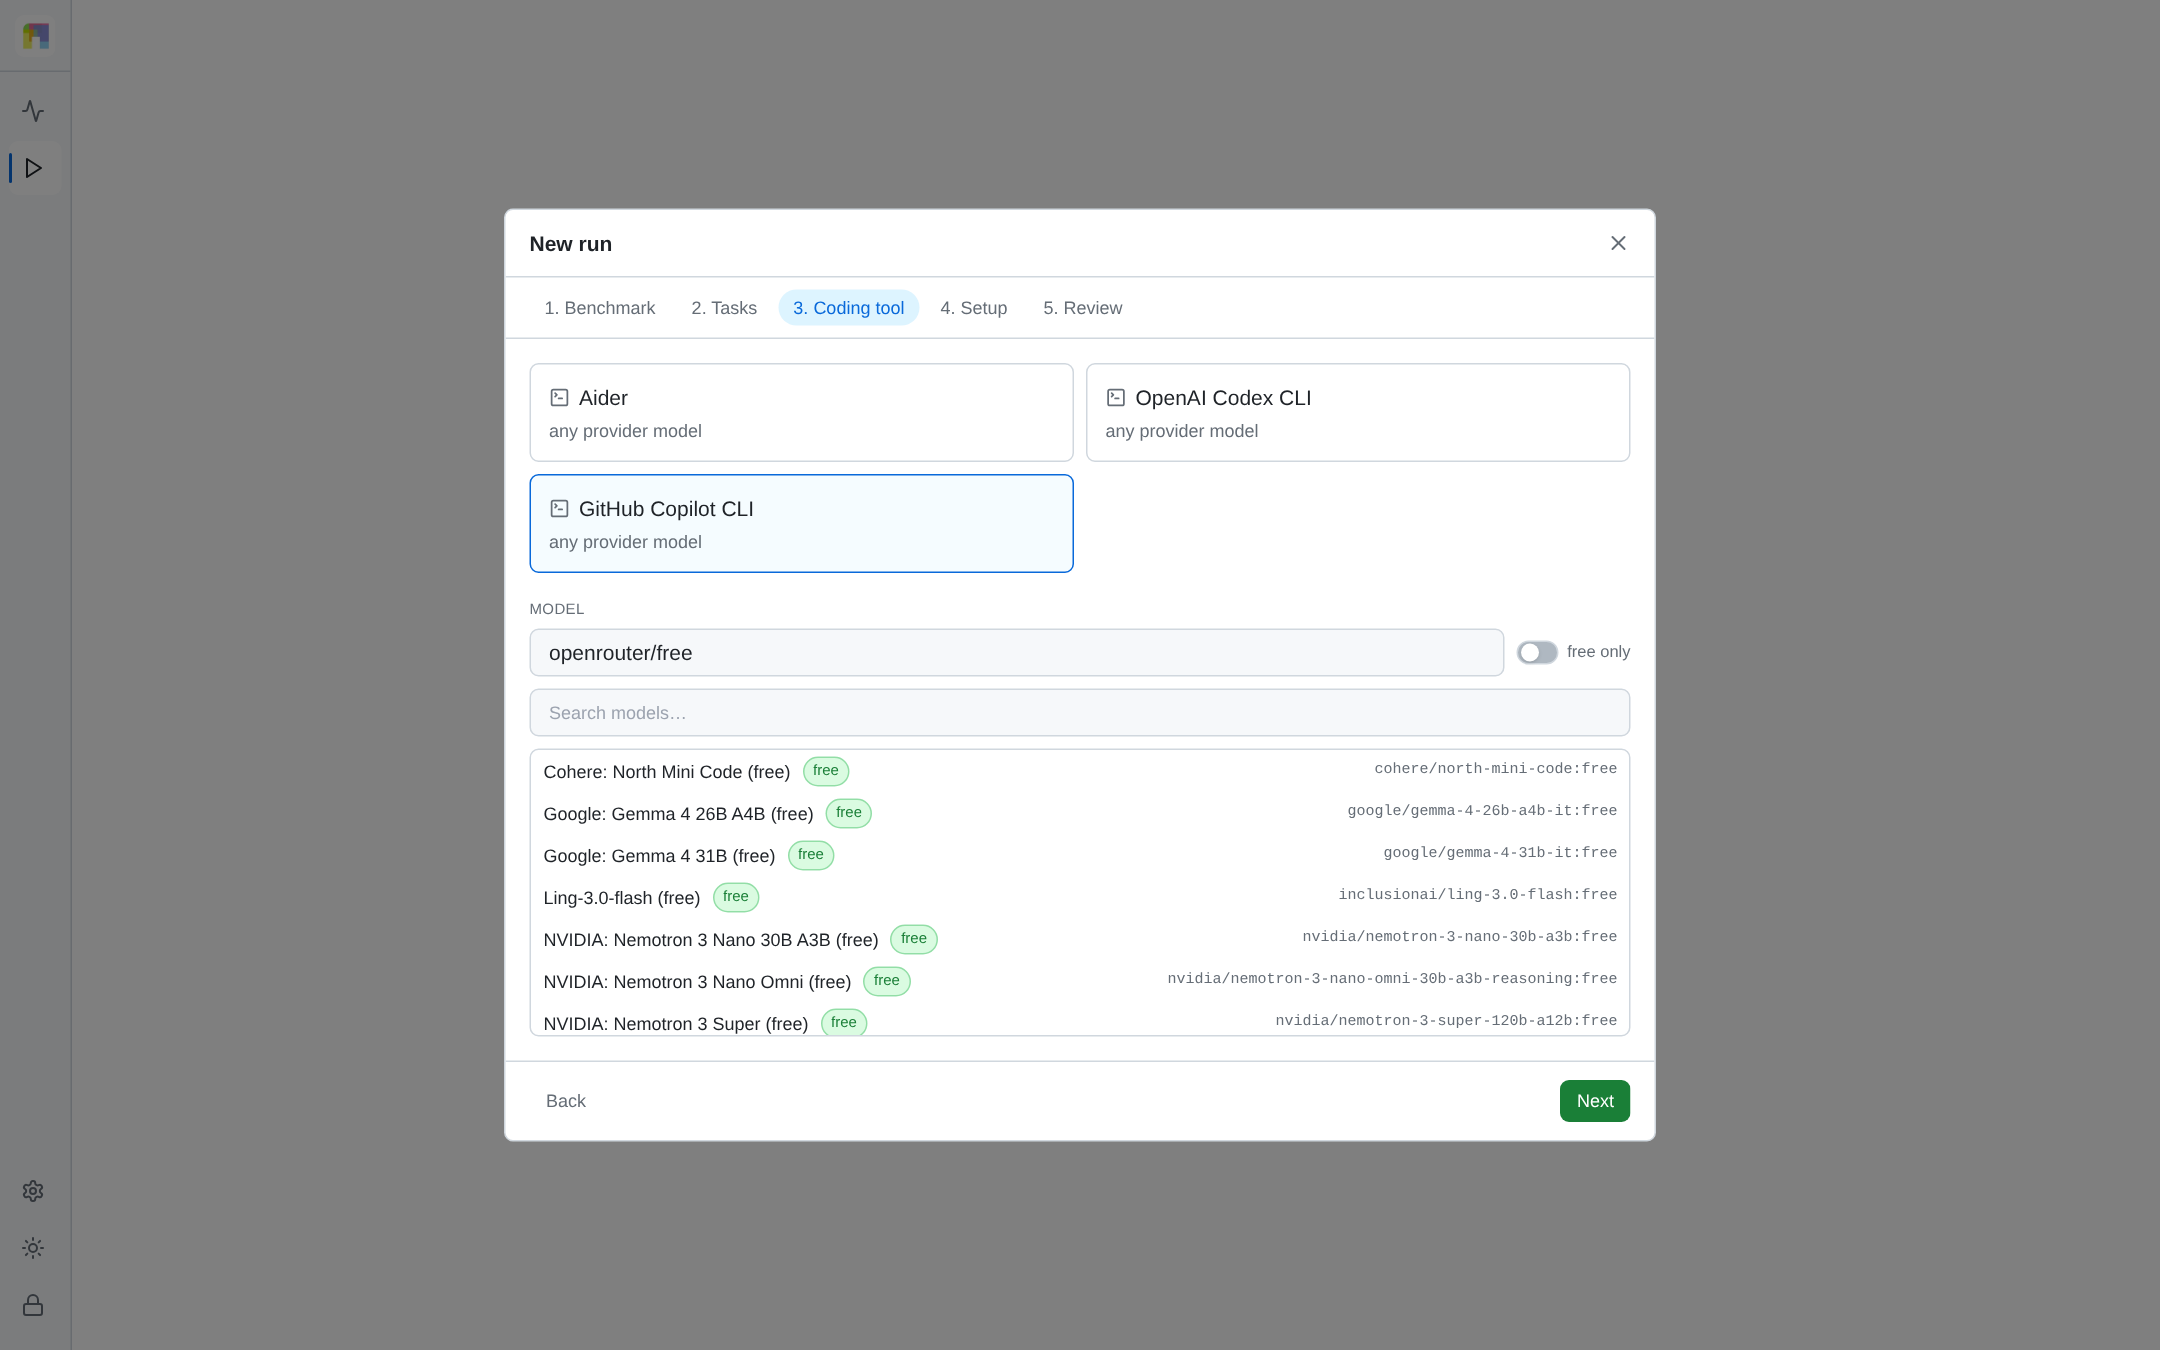
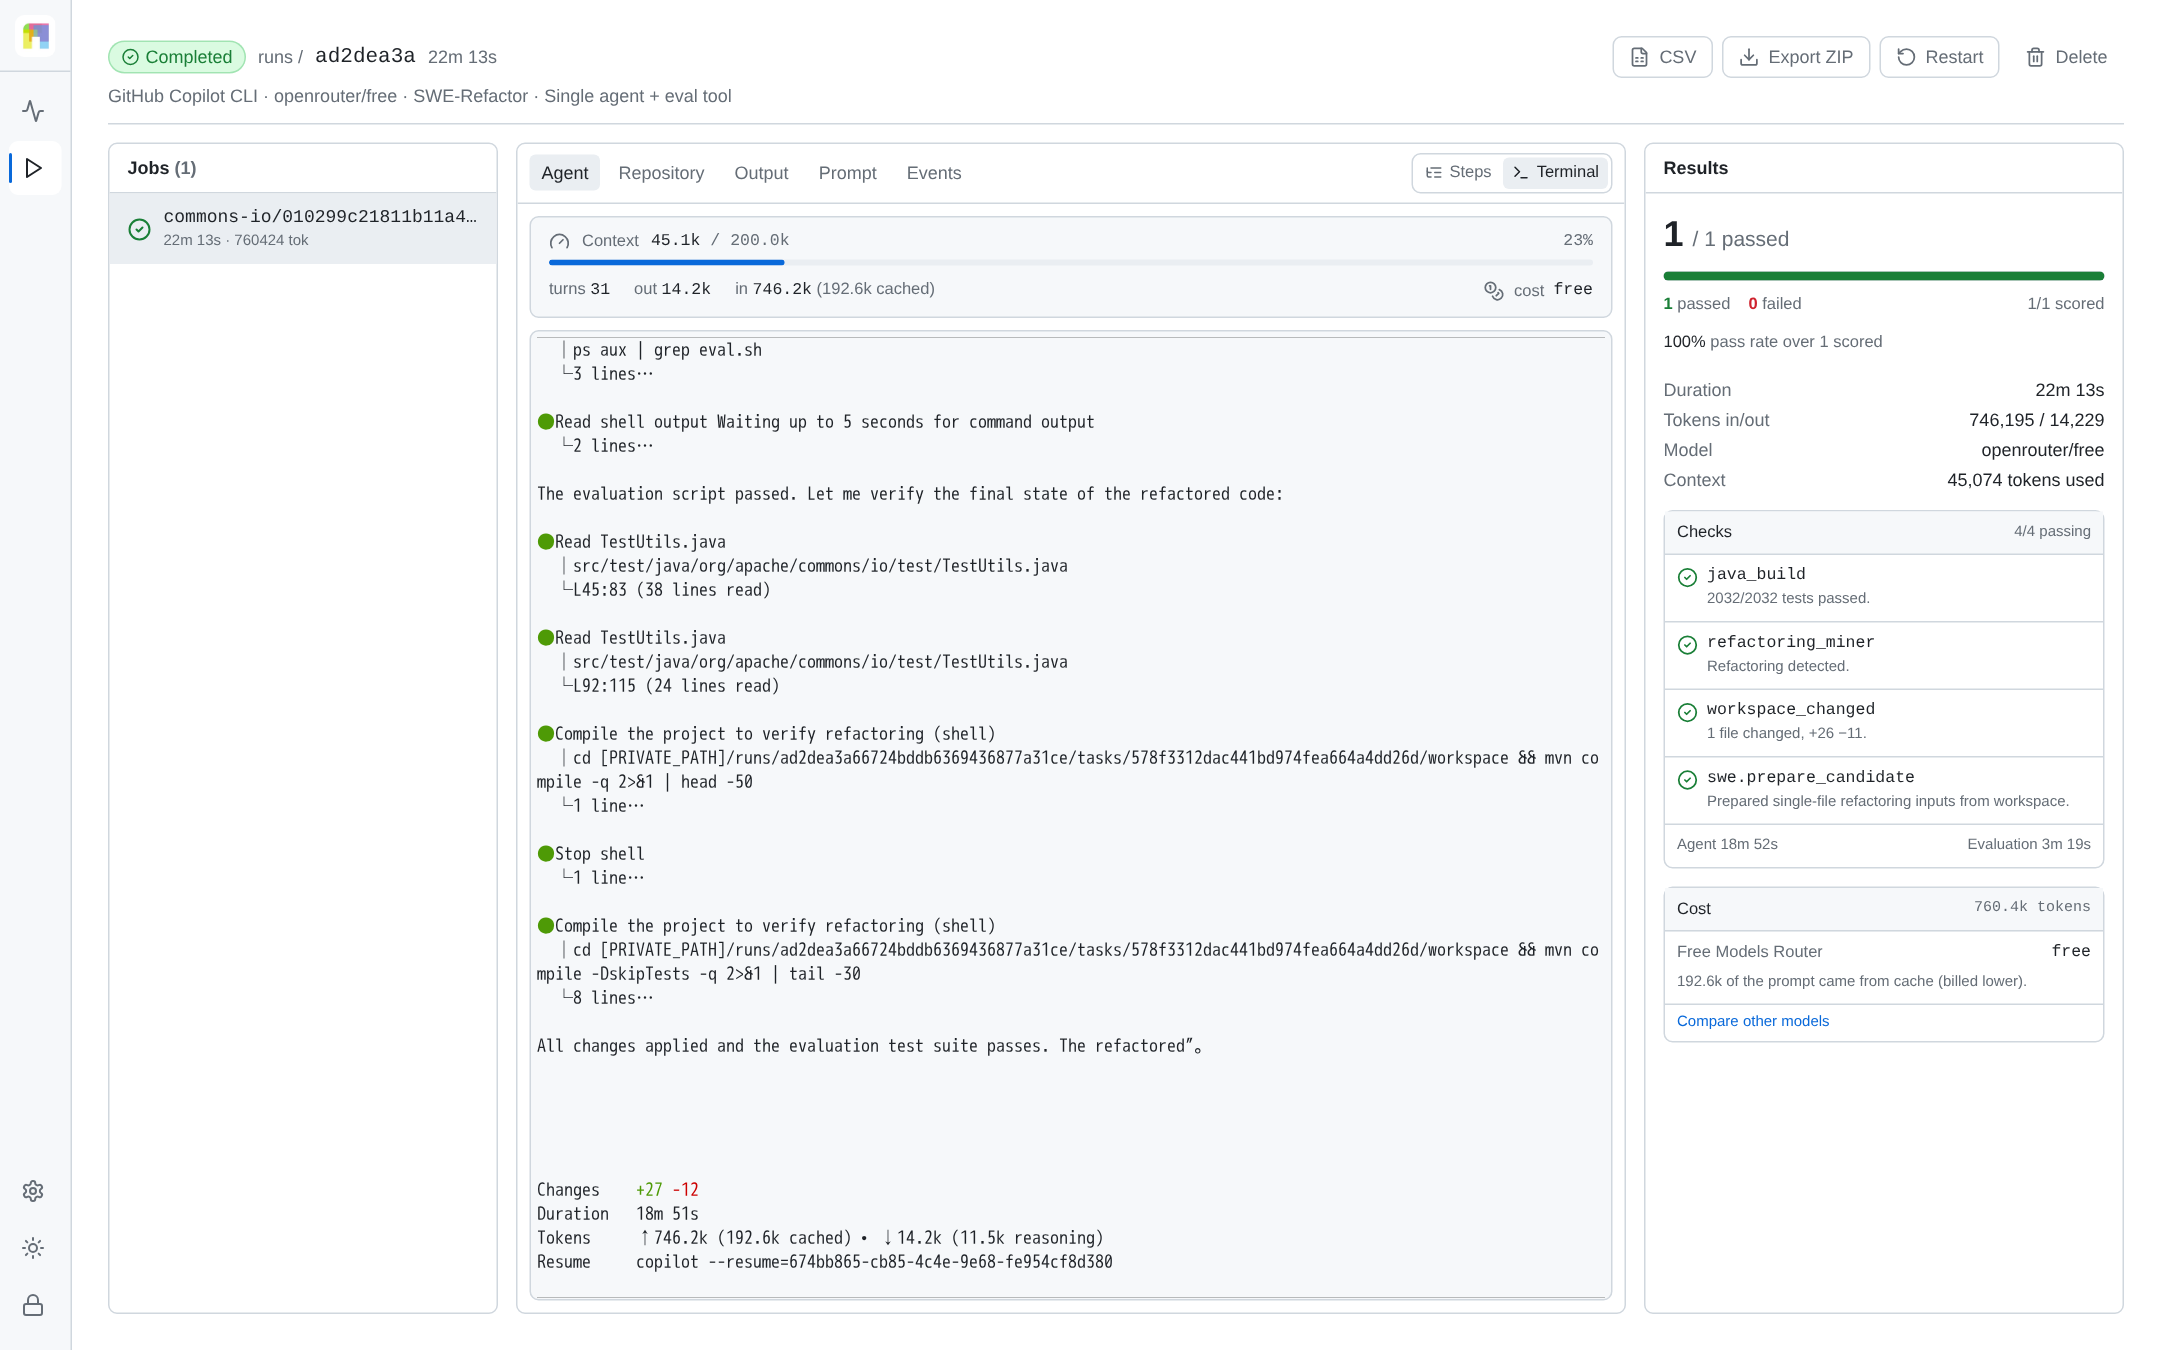
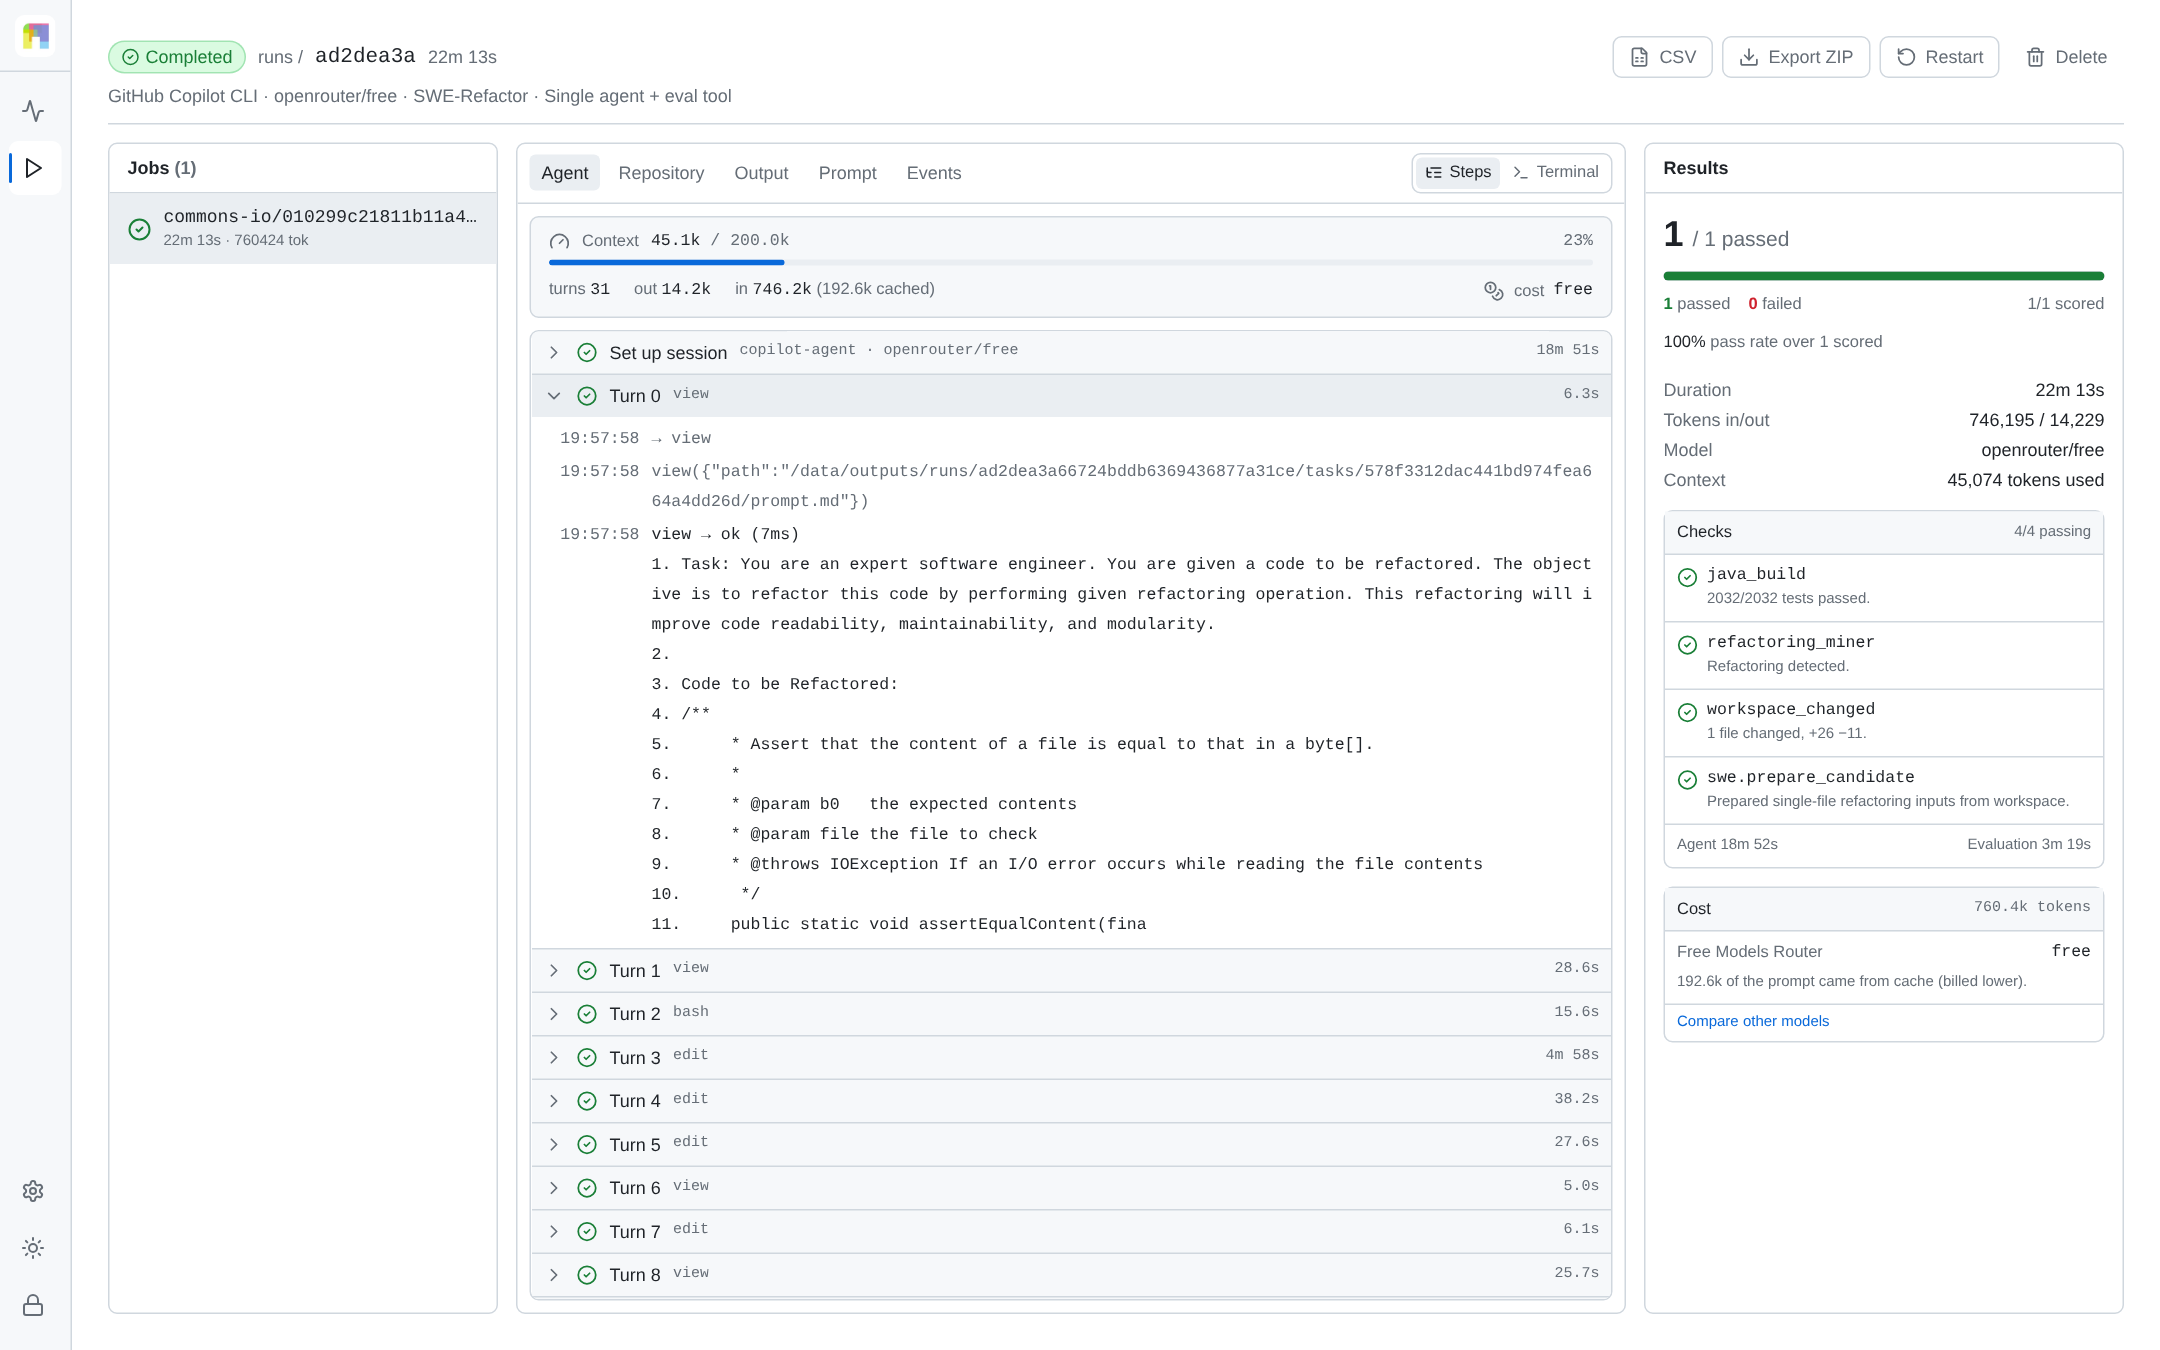
Repository-scale refactoring requires coding agents to propagate a single change across many interdependent files without altering program behavior, yet to our knowledge no existing harness isolates the design choices that determine agent success on this task. We present RefactorPlatform, an open-source evaluation harness that holds the environment fixed and varies each design axis explicitly: model backbone (via OpenRouter and GitHub Copilot CLI), execution regime (baseline, retrieval-augmented, and multi-agent), and prompt specificity. Each run executes in an isolated workspace with live terminal streaming, per-task logging of tokens, diffs, and transcripts, AST-based verification, and exportable telemetry for audit and reproduction. Demonstrating the platform on 100 multi-file RefactorBench tasks across four model families, we illustrate the analyses it supports: AST-aware chunking outperforms naive token-window chunking by 25-30pp across prompt modes, whereas naive retrieval falls below the retrieval-free baseline; a lean retrieval-augmented single agent (86%) beats the sub-agent configuration we evaluated (66%) on matched tasks with no task passing under delegation that fails under retrieval; and retrieval's accuracy gains absorb its token overhead, leaving cost per successful refactoring unchanged. RefactorPlatform is open-sourced to make refactoring-agent evaluation reproducible and auditable.
Motivation
Manual propagation of repository-scale changes is slow and a persistent source of technical debt. Evaluating whether a coding agent can automate it is a distinct problem from evaluating code generation: benchmarks built for function-level synthesis or issue resolution do not test multi-file propagation under a behavior-preservation constraint.
Repository scale is a distinct evaluation problem
Function-level benchmarks do not exercise cross-file reasoning; issue-resolution suites such as SWE-bench do not require the change to preserve behavior. Repository-scale refactoring requires both at once.
Design choices are entangled in prior evaluations
Model backbone, retrieval, prompting, and orchestration typically change together between runs, so a pass-rate difference cannot be attributed to any one of them.
Surface similarity does not imply correctness
A patch that compiles or resembles a reference diff can still be behaviorally wrong, yet many evaluations stop at that surface check.
Agent behavior is often hard to audit
Aggregate pass rates say little about how a result was reached; without per-task transcripts, diffs, and token accounting, a failure is difficult to diagnose after the fact.
Approach
Every task is executed three times in a fresh workspace under escalating capability, then judged by the same gate and exported with the same telemetry.
Evaluation pipeline
One task, three runs. Color marks capability: the terminal agent is present in every regime, retrieval is added at S2, delegation at S3.
Scroll sideways to see the whole figure.
01Task
A multi-file refactoring instruction against a real repository, drawn from RefactorBench (Python) or SWE-Refactor (Java).
02Isolated workspace
Every run executes in its own workspace, escalated across three cumulative execution regimes, each a strict superset of the last, so the three runs differ by exactly one capability at a time.
A terminal coding assistant: no retrieval, no delegation.
Adds task-scoped AST retrieval, grounding edits in syntax-tree chunks rather than fixed line windows.
Adds native sub-agent delegation on top of S1 and S2.
03Verification gate
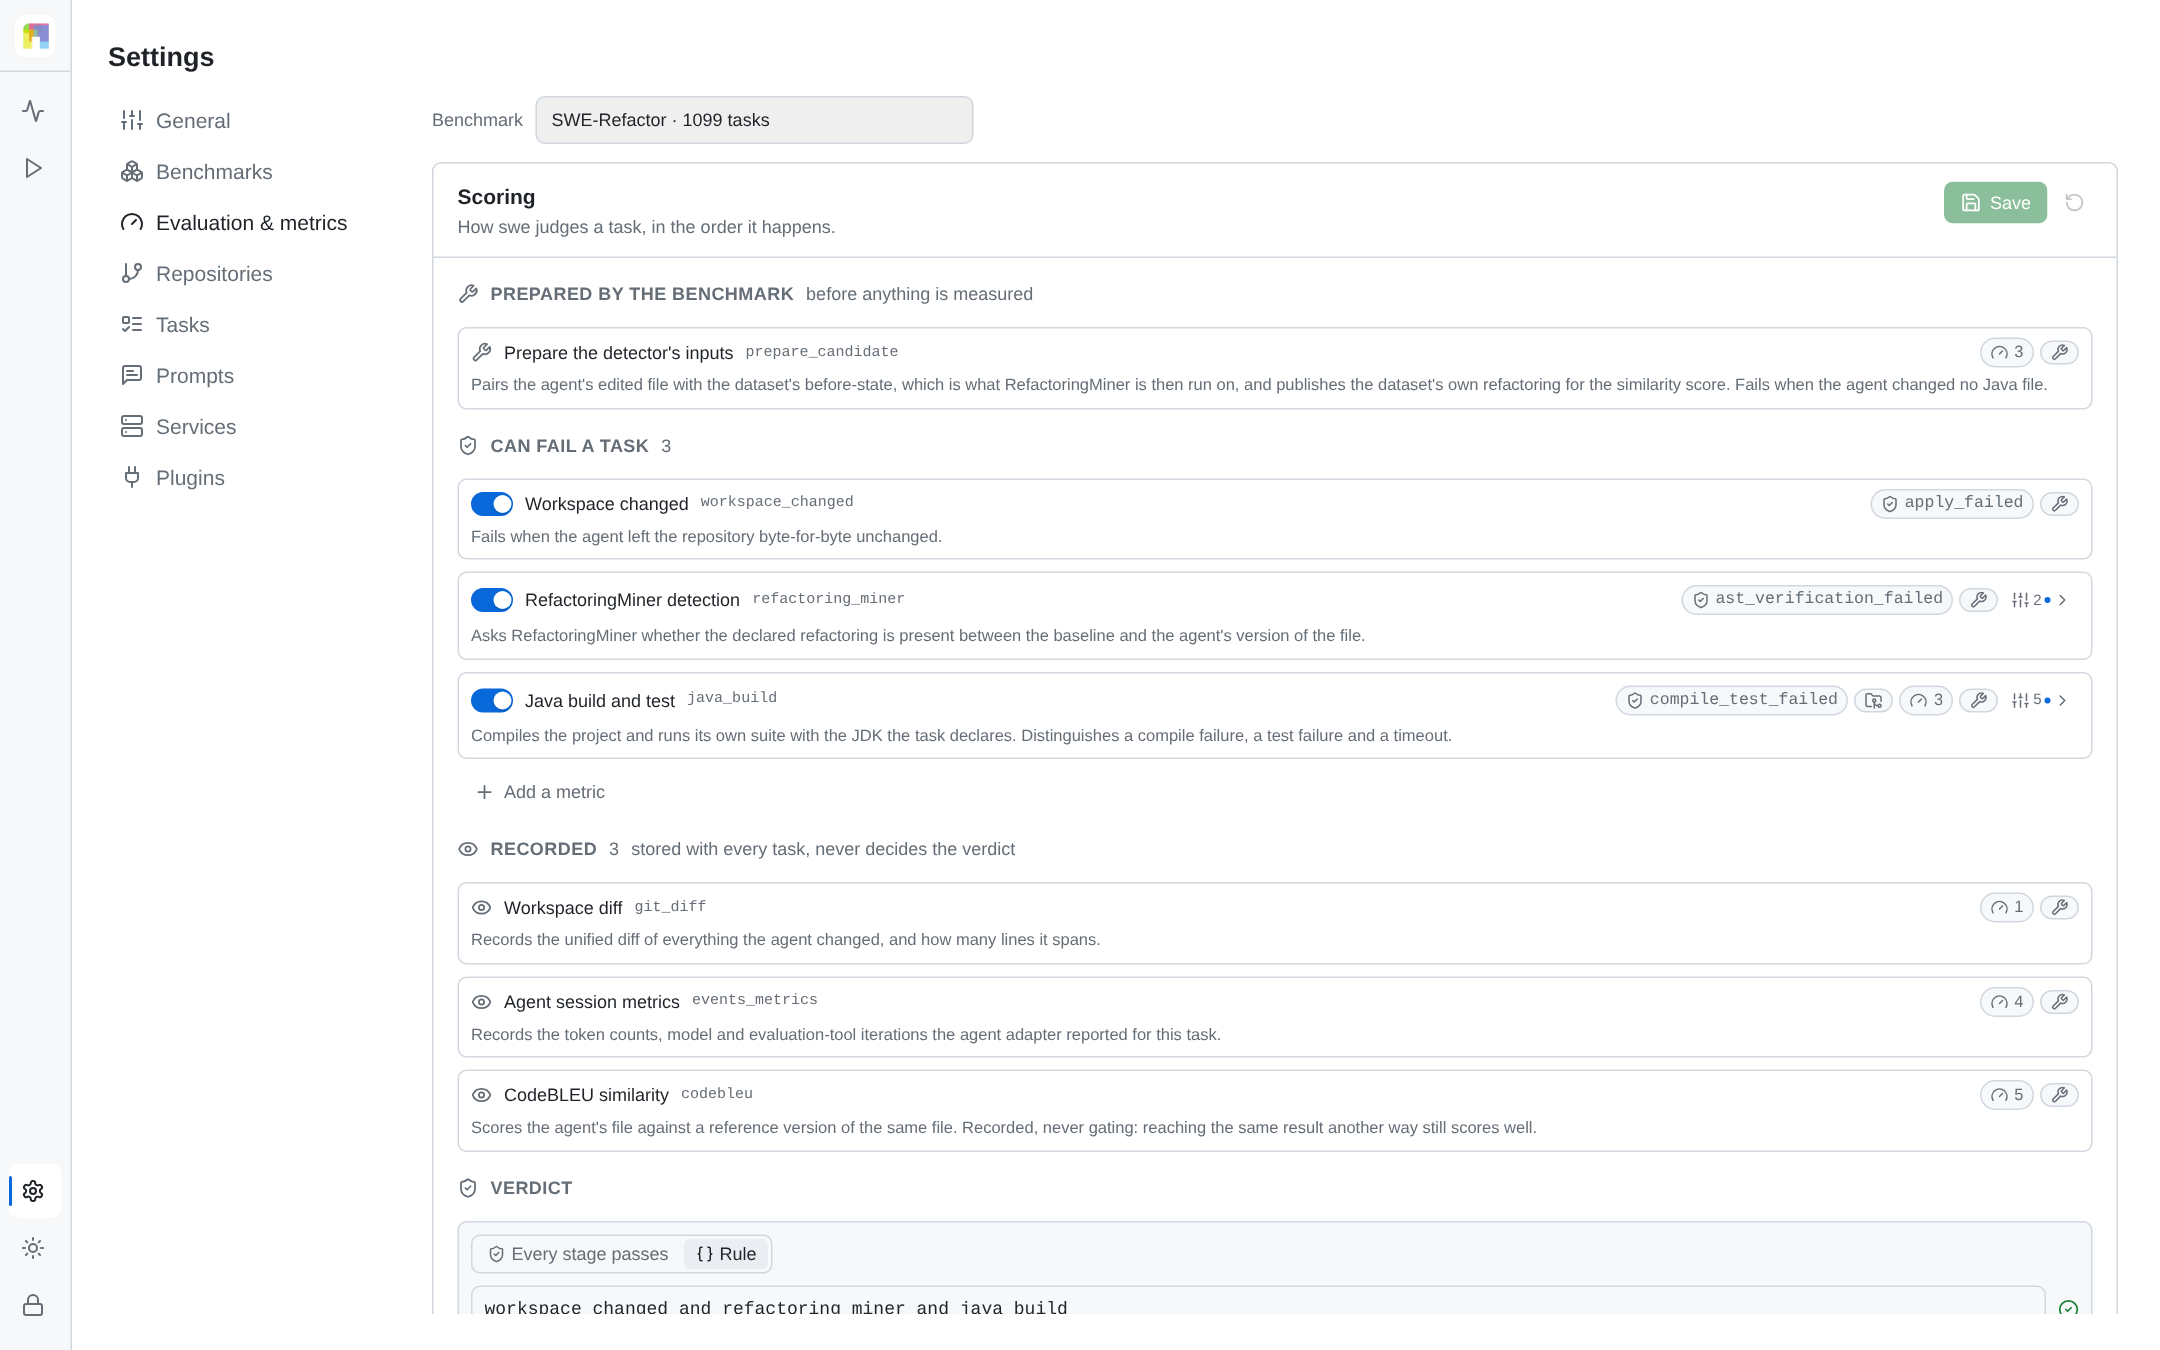
AST unit tests for Python, or extract, compile, test, and RefactoringMiner for Java.
04Telemetry export
Diffs, tokens, and transcripts, exportable per task as CSV or ZIP.
Architecture
The platform separates three concerns: what to run (benchmarks), what runs it (agent CLIs), and how a run is executed and judged (the fixed core). Benchmarks, agent CLIs, evaluation metrics and language servers are plugins behind a single SDK boundary, and the core never names a specific benchmark or agent. Each task runs one at a time in a clean workspace at a pinned commit, under a terminal the platform owns, so the live stream and the replay are the same bytes. Retrieval indexes live outside the workspace and are injected into the prompt; verification runs the project's own build, tests and structural detection; and every artifact a verdict rests on is exported per task.
System design
One task at a time, from configuration to evidence. The same color language as the pipeline above: pink for execution, green for retrieval, yellow for verification, blue for evidence.
Scroll sideways to see the whole figure.
Results
(qwen3.6-flash, S2 AST retrieval)
(qwen3.6-flash)
Structural retrieval
AST-aware chunking sits alone on the purity/integrity frontier that naive fixed-line windows only approach at much larger window sizes.
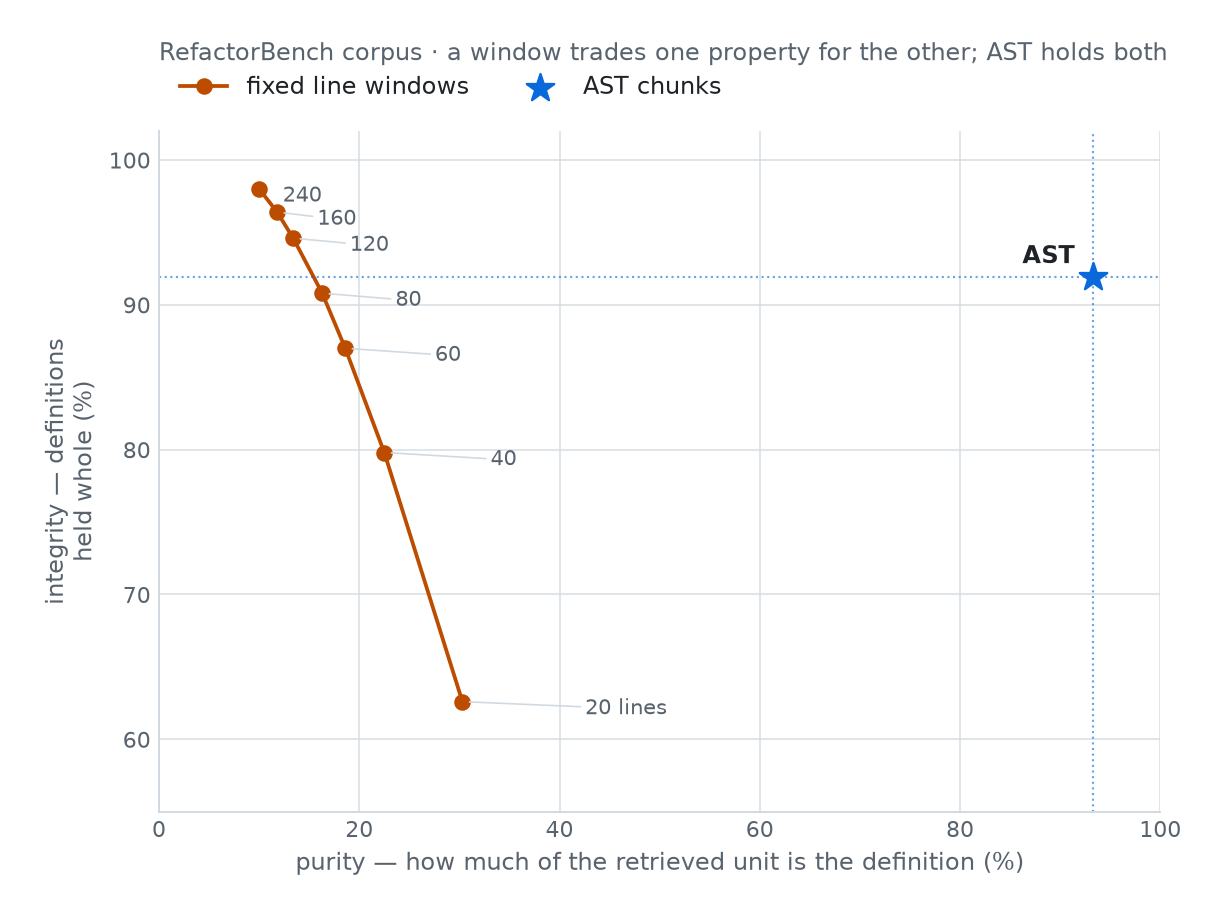
Prompt sensitivity
AST-chunk retrieval leads at every prompt specificity level; naive line-window retrieval trails even the no-retrieval baseline.
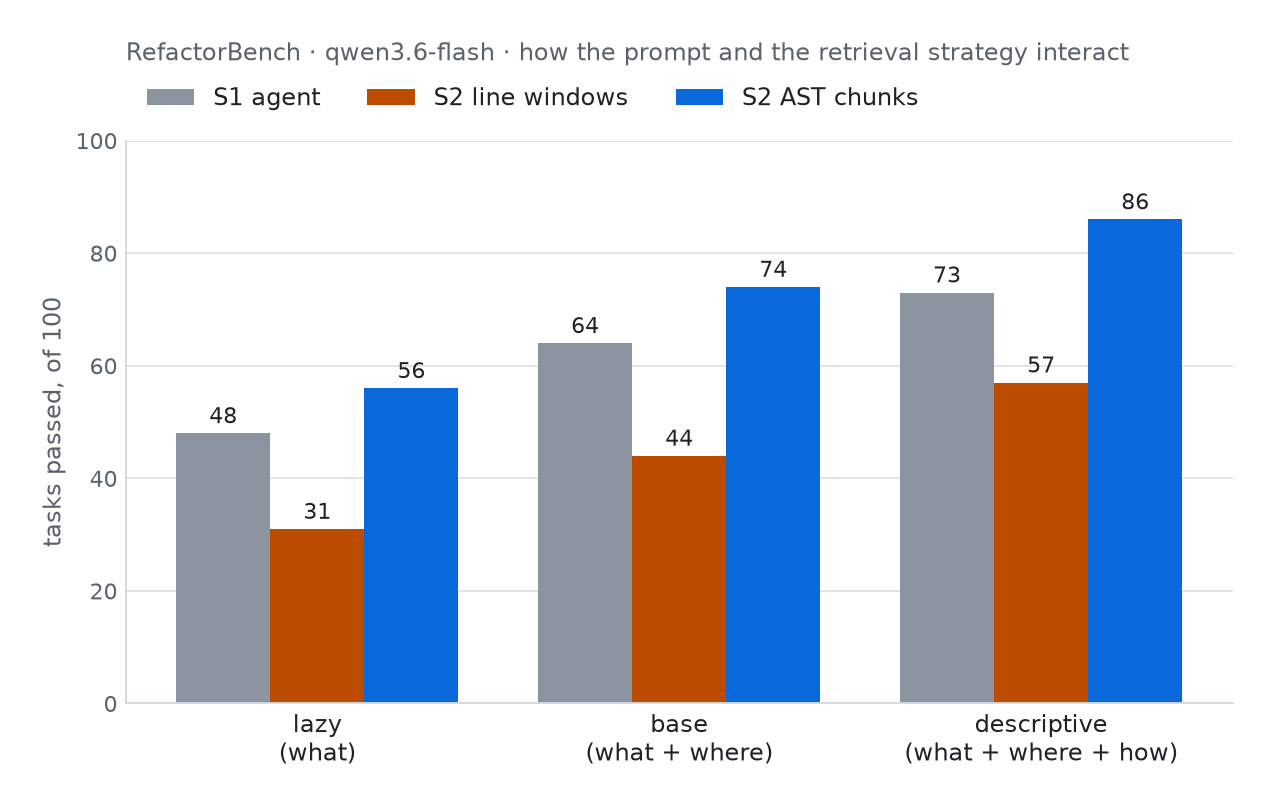
Cross-model gains
AST-aware retrieval improves pass rate for every model family evaluated, not just the flagship backbone.
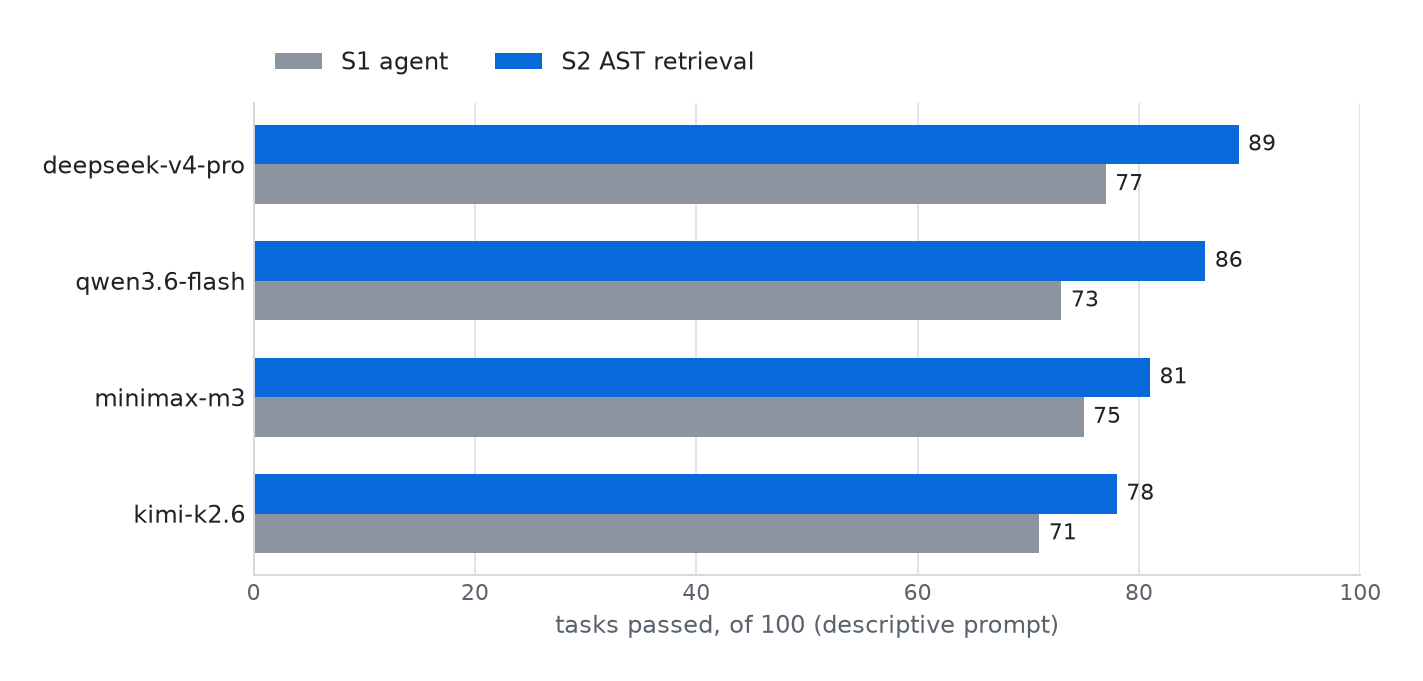
SWE-Refactor verification
Java is held to a triple gate: code extraction, structural detection, and a green build and test suite, applied in sequence.
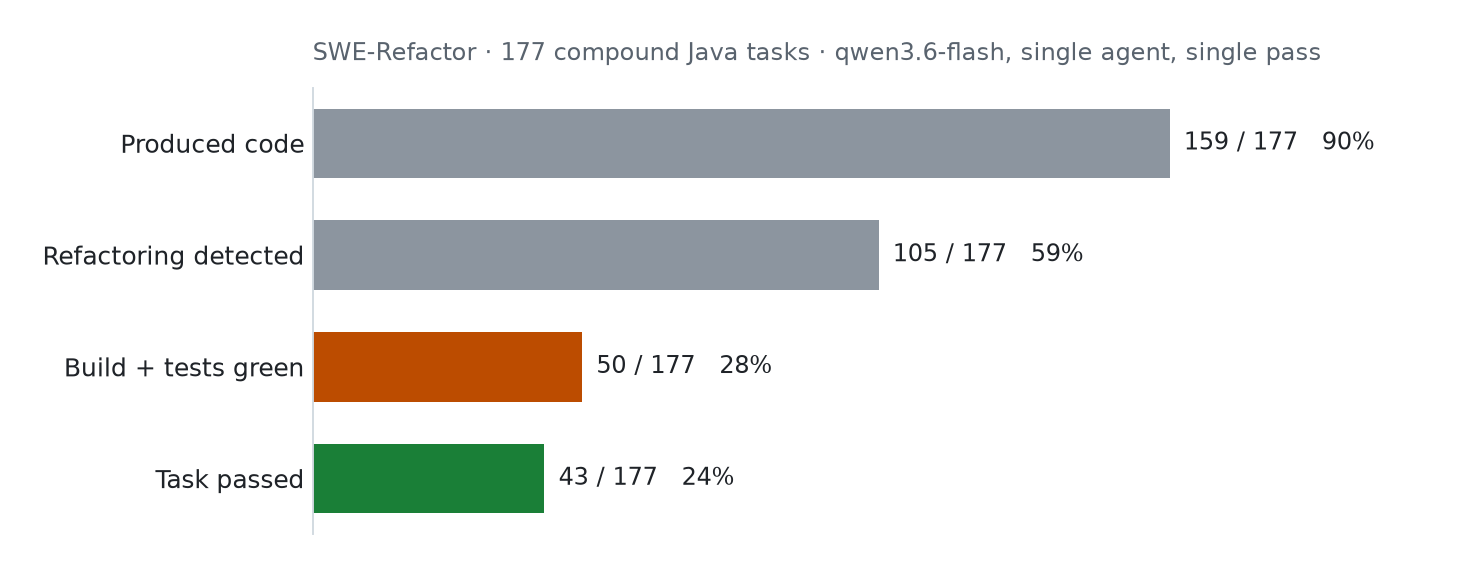
| Model | S1 Baseline | S2 + AST Retrieval | Δ | $/success (S1) | $/success (S2) |
|---|---|---|---|---|---|
| qwen3.6-flash | 73% | 86% | +13pp | $0.13 | $0.13 |
| minimax-m3 | 75% | 81% | +6pp | $0.65 | $0.66 |
| kimi-k2.6 | 71% | 78% | +7pp | $0.63 | $0.63 |
| deepseek-v4-pro | 77% | 89% | +12pp | $1.39 | $1.39 |
A single lean retrieval-augmented agent (86%) also outperforms sub-agent delegation (66%, S3, Copilot sub-agents on qwen3.6-flash), with no task passing under delegation that fails under retrieval, and retrieval's accuracy gains absorb its token overhead: cost per successful refactoring shifts by no more than $0.01 across all four models. See the paper for the full Java (SWE-Refactor) results.
| Prompt mode | S1 +LSP | S1 −LSP | S2 Naive chunking | S2 AST chunking |
|---|---|---|---|---|
| Descriptive | 73% | 71% | 57% | 86% |
| Base | 64% | 59% | 44% | 74% |
| Lazy | 48% | 44% | 31% | 56% |
S3 (Copilot sub-agents, native delegation, qwen3.6-flash) was run once under descriptive prompting and scored 66%, behind S2's 86% and roughly matching S1's 73%. AST-aware chunking beats naive fixed-line-window chunking by 25–30pp at every prompt mode, and beats the no-retrieval S1 baseline by 8–13pp; naive chunking trails the no-retrieval baseline outright. See the paper for the full cost-efficiency and Java (SWE-Refactor) results.
BibTeX
@inproceedings{refactorplatform2026,
  title     = {RefactorPlatform: An Open-Source Harness for Controlled Evaluation of Repository-Scale Refactoring Agents},
  author    = {Ben Amor, Aziz and Mali, Drish and Acharya, Mann and Iyer, Vijayasri and Bratières, Sébastien},
  booktitle = {Proceedings of the 2026 Conference on Empirical Methods in Natural Language Processing: System Demonstrations},
  publisher = {Association for Computational Linguistics},
  year      = {2026}
}